

本文详细讲解如何使用 JavaScript 实现二叉搜索树(BST)。内容涵盖树的基本结构定义、核心接口设计,重点解析 contains 查找、add 插入以及复杂的 remove 删除操作。通过代码示例演示有序遍历、前驱节点查找及平衡性注意事项,帮助开发者掌握 BST 在 JS 中的完整实现逻辑。
二叉搜索树基础与结构
在计算机科学领域,二叉搜索树(Binary Search Tree, BST)是一种应用广泛且备受关注的非线性数据结构。它通常作为首个引入具有非线性插入逻辑的数据结构出现在学习路径中。二叉搜索树的结构类似于双链表,每个节点存储数据以及指向其他两个节点的指针,区别在于节点间的关联方式。在 BST 中,这些指针通常被命名为“左”和“右”,用于指示与当前节点值相关的子树范围。以下是一个基础的 JavaScript 节点实现示例:
var node = {
  value: 125,
  left: null,
  right: null
};
顾名思义,二叉搜索树呈现出分层的树状结构。首个插入的元素成为根节点,后续添加的值则作为根节点的祖先节点依次加入。BST 的关键特性在于节点值的唯一性与有序性:左子树中的所有值必须严格小于当前节点的值,而右子树中的所有值必须严格大于当前节点的值。基于这一特性,查找操作变得高效:若目标值小于当前节点,则向左子树移动;若大于当前节点,则向右子树移动。由于重复值会破坏这种有序关系,BST 中不允许存在重复节点。下图展示了一个简单的二叉搜索树结构:
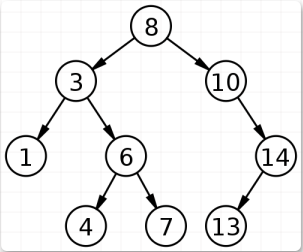
上图展示了一个根节点值为 8 的二叉搜索树。当插入值 3 时,因其小于 8,成为根的左子节点。接着插入值 1,由于 1 小于 8(向左)且 1 小于 3(再向左),它成为 3 的左子节点。插入值 10 时,因 10 大于 8,成为根的右子节点。以此类推,继续处理值 6、4、7、14 和 13。该树的深度为 3,表示距离根节点最远的节点层级为第三层。
二叉搜索树天然保持排序状态,这使得数据查找非常迅速,因为每次比较都能排除一半的可能性。通过限制需要检查的节点数量,搜索效率显著提升。例如,在上述树中查找值 6:从根节点 8 开始,因 6 小于 8 向左移动至节点 3;因 6 大于 3 向右移动,最终找到目标值。在此过程中,仅需访问三个节点,而非遍历全部九个节点,体现了 BST 的搜索优势。
JavaScript 接口定义与查找实现
要在 JavaScript 中构建二叉搜索树,首先需要定义其基本接口:
function BinarySearchTree() {
  this._root = null;
}

BinarySearchTree.prototype = {

  //restore constructor
  constructor: BinarySearchTree,

  add: function (value){
  },

  contains: function(value){
  },

  remove: function(value){
  },

  size: function(){
  },

  toArray: function(){
  },

  toString: function(){
  }

};
该基础接口与其他数据结构类似,包含添加和删除值的方法。此外,还添加了 size()、toArray() 和 toString() 等便捷方法,以增强 JavaScript 中的实用性。
理解二叉搜索树的最佳切入点是从 contains() 方法开始。该方法接收一个值作为参数,若该值存在于树中则返回 true,否则返回 false。此方法遵循标准的二叉搜索算法:
BinarySearchTree.prototype = {

  //more code

  contains: function(value){
    var found    = false,
      current   = this._root

    //make sure there's a node to search
    while(!found && current){

      //if the value is less than the current node's, go left
      if (value < current.value){
        current = current.left;

      //if the value is greater than the current node's, go right
      } else if (value > current.value){
        current = current.right;

      //values are equal, found it!
      } else {
        found = true;
      }
    }

    //only proceed if the node was found
    return found;
  },

  //more code

};
搜索过程从树的根节点开始。若树中尚未添加数据,可能不存在根节点,因此需进行空值检查。遍历过程遵循前述简单算法:若目标值小于当前节点,向左移动;若大于当前节点,向右移动。每次迭代更新 current 指针,直到找到目标值(此时 found 设为 true)或在该方向上无更多节点(表明值不在树中)。
节点插入与树遍历方法
contains() 中使用的方法同样适用于插入新值。主要区别在于,插入操作旨在寻找放置新值的位置,而非查找现有值:
BinarySearchTree.prototype = {

  //more code

  add: function(value){
    //create a new item object, place data in
    var node = {
        value: value,
        left: null,
        right: null
      },

      //used to traverse the structure
      current;

    //special case: no items in the tree yet
    if (this._root === null){
      this._root = node;
    } else {
      current = this._root;

      while(true){

        //if the new value is less than this node's value, go left
        if (value < current.value){

          //if there's no left, then the new node belongs there
          if (current.left === null){
            current.left = node;
            break;
          } else {
            current = current.left;
          }

        //if the new value is greater than this node's value, go right
        } else if (value > current.value){

          //if there's no right, then the new node belongs there
          if (current.right === null){
            current.right = node;
            break;
          } else {
            current = current.right;
          }

        //if the new value is equal to the current one, just ignore
        } else {
          break;
        }
      }
    }
  },

  //more code

};
在二叉搜索树中添加值时,需处理特殊情况:若树中尚无根节点,直接将根节点设置为新值即可。对于其他情况,基本算法与 contains() 完全一致:新值小于当前节点向左,大于则向右。关键区别在于,当无法继续前进时,该位置即为新值的插入点。若需向左但左子节点为空,则新值成为左子节点(右子节点同理)。由于 BST 不允许重复,若遇到具有相同值的节点,插入操作将终止。
在讨论 size() 方法之前,需深入探讨树遍历。计算二叉搜索树的大小需要访问每个节点。BST 通常支持多种遍历方式,其中最常用的是有序遍历(In-order Traversal)。通过先处理左子树,再处理当前节点,最后处理右子树,有序遍历确保节点按从左到右的正确排序顺序被处理。虽然 size() 方法对遍历顺序不敏感,但 toArray() 方法依赖于此顺序。鉴于两种方法均需遍历,决定添加一个通用的 traverse() 方法:
BinarySearchTree.prototype = {

  //more code

  traverse: function(process){

    //helper function
    function inOrder(node){
      if (node){

        //traverse the left subtree
        if (node.left !== null){
          inOrder(node.left);
        }

        //call the process method on this node
        process.call(this, node);

        //traverse the right subtree
        if (node.right !== null){
          inOrder(node.right);
        }
      }
    }

    //start with the root
    inOrder(this._root);
  },

  //more code

};
该方法接收一个 process 参数,这是一个将在每个节点上执行的函数。内部定义了一个名为 inOrder() 的辅助函数用于递归遍历。注意,仅当当前节点存在时才进行左右递归(以避免处理 null 节点)。traverse() 方法从根节点开始按序遍历,process() 函数负责处理每个节点。利用此方法可实现 size()、toArray() 和 toString():
BinarySearchTree.prototype = {

  //more code

  size: function(){
    var length = 0;

    this.traverse(function(node){
      length++;
    });

    return length;
  },

  toArray: function(){
    var result = [];

    this.traverse(function(node){
      result.push(node.value);
    });

    return result;
  },

  toString: function(){
    return this.toArray().toString();
  },

  //more code

};
size() 和 toArray() 均调用 traverse() 方法并传入特定函数。在 size() 中,函数用于递增长度变量;在 toArray() 中,函数将节点值添加到数组。toString() 方法在调用 toArray() 后将返回的数组转换为字符串并返回结果。
节点删除逻辑与平衡性处理
删除节点时,需判断其是否为根节点。根节点的处理方式与其他节点类似,但显著区别在于根节点在删除后需设置为新值。为简化代码,此处将根节点处理视为 JavaScript 代码中的特例。
删除节点的第一步是确定目标节点是否存在:
BinarySearchTree.prototype = {

  //more code here

  remove: function(value){

    var found    = false,
      parent   = null,
      current   = this._root,
      childCount,
      replacement,
      replacementParent;

    //make sure there's a node to search
    while(!found && current){

      //if the value is less than the current node's, go left
      if (value < current.value){
        parent = current;
        current = current.left;

      //if the value is greater than the current node's, go right
      } else if (value > current.value){
        parent = current;
        current = current.right;

      //values are equal, found it!
      } else {
        found = true;
      }
    }

    //only proceed if the node was found
    if (found){
      //continue
    }

  },
  //more code here

};
remove() 方法的第一部分是利用二叉搜索定位待删除节点:若值小于当前节点向左移动,大于则向右移动。遍历时同时跟踪 parent 节点,因为最终需从其父节点中移除该节点。当 found 为 true 时,current 的值即为目标节点。
删除节点时需考虑三种情况:
- 叶子节点(无子节点)
- 仅有一个子节点的节点
- 拥有两个子节点的节点
删除非叶子节点意味着必须移动值以维持树的正确排序。前两种情况相对简单:直接删除叶子节点,或用一个子节点替换单子节点。最后一种情况较为复杂,需后续详细处理。
在了解节点删除逻辑前,需明确节点拥有的子节点数量。确定数量后,需判断该节点是否为根节点,从而形成简明的决策流程:
BinarySearchTree.prototype = {

  //more code here

  remove: function(value){

    var found    = false,
      parent   = null,
      current   = this._root,
      childCount,
      replacement,
      replacementParent;

    //find the node (removed for space)

    //only proceed if the node was found
    if (found){

      //figure out how many children
      childCount = (current.left !== null ? 1 : 0) +
             (current.right !== null ? 1 : 0);

      //special case: the value is at the root
      if (current === this._root){
        switch(childCount){

          //no children, just erase the root
          case 0:
            this._root = null;
            break;

          //one child, use one as the root
          case 1:
            this._root = (current.right === null ?
                   current.left : current.right);
            break;

          //two children, little work to do
          case 2:

            //TODO

          //no default

        }

      //non-root values
      } else {

        switch (childCount){

          //no children, just remove it from the parent
          case 0:
            //if the current value is less than its
            //parent's, null out the left pointer
            if (current.value < parent.value){
              parent.left = null;

            //if the current value is greater than its
            //parent's, null out the right pointer
            } else {
              parent.right = null;
            }
            break;

          //one child, just reassign to parent
          case 1:
            //if the current value is less than its
            //parent's, reset the left pointer
            if (current.value < parent.value){
              parent.left = (current.left === null ?
                      current.right : current.left);

            //if the current value is greater than its
            //parent's, reset the right pointer
            } else {
              parent.right = (current.left === null ?
                      current.right : current.left);
            }
            break;

          //two children, a bit more complicated
          case 2:

            //TODO

          //no default

        }

      }

    }

  },

  //more code here

};
处理根节点时,直接覆盖其值即可。对于非根节点,需根据待删除节点的值设置父节点上的相应指针:若删除值小于父节点,left 指针需重置为 null(无子节点)或删除节点的 left 指针;若删除值大于父节点,right 指针需重置为 null 或删除节点的 right 指针。
如前所述,删除拥有两个子节点的节点是最复杂的操作。下图展示了二叉搜索树的一种表示形式:
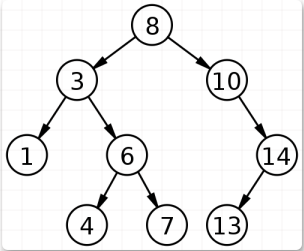
根节点为 8,左子节点为 3。若删除 3,有两种可能性:1(3 的左孩子,称为有序前驱)或 4(右子树的最左孩子,称为有序后继)均可替代 3。
这两种选项均适用。查找有序前驱(删除值之前的值)需检查待删除节点的左子树,并选择最右侧的子节点;查找有序后继(删除值之后的值)则反向操作,检查最左侧的右子树。每种情况均需另一次树遍历来完成操作:
BinarySearchTree.prototype = {

  //more code here

  remove: function(value){

    var found    = false,
      parent   = null,
      current   = this._root,
      childCount,
      replacement,
      replacementParent;

    //find the node (removed for space)

    //only proceed if the node was found
    if (found){

      //figure out how many children
      childCount = (current.left !== null ? 1 : 0) +
             (current.right !== null ? 1 : 0);

      //special case: the value is at the root
      if (current === this._root){
        switch(childCount){

          //other cases removed to save space

          //two children, little work to do
          case 2:

            //new root will be the old root's left child
            //...maybe
            replacement = this._root.left;

            //find the right-most leaf node to be
            //the real new root
            while (replacement.right !== null){
              replacementParent = replacement;
              replacement = replacement.right;
            }

            //it's not the first node on the left
            if (replacementParent !== null){

              //remove the new root from it's
              //previous position
              replacementParent.right = replacement.left;

              //give the new root all of the old
              //root's children
              replacement.right = this._root.right;
              replacement.left = this._root.left;
            } else {

              //just assign the children
              replacement.right = this._root.right;
            }

            //officially assign new root
            this._root = replacement;

          //no default

        }

      //non-root values
      } else {

        switch (childCount){

          //other cases removed to save space

          //two children, a bit more complicated
          case 2:

            //reset pointers for new traversal
            replacement = current.left;
            replacementParent = current;

            //find the right-most node
            while(replacement.right !== null){
              replacementParent = replacement;
              replacement = replacement.right;
            }

            replacementParent.right = replacement.left;

            //assign children to the replacement
            replacement.right = current.right;
            replacement.left = current.left;

            //place the replacement in the right spot
            if (current.value < parent.value){
              parent.left = replacement;
            } else {
              parent.right = replacement;
            }

          //no default

        }

      }

    }

  },

  //more code here

};
拥有两个子节点的根节点与非根节点的删除代码几乎相同。此实现始终通过查看左子树并查找最右侧子节点来确定有序前驱。遍历过程使用 while 循环中的 replacement 和 replacementParent 变量完成。replacement 节点最终替换 current 节点,因此需将其父级的 right 指针设置为 replacement 的 left 指针,从而将其从原位置移除。对于根节点,若 replacement 是根节点的直接子节点,replacementParent 将为 null,此时仅需将 replacement 的 right 指针设置为 root 的 right 指针。最后一步是将替换节点分配到正确位置:对于根节点,replacement 设为新根;对于非根节点,replacement 被分配到原始 parent 上的适当位置。
说明:始终使用有序前驱替换节点可能导致树不平衡,即大多数值集中在树的一侧。不平衡树会降低搜索效率,因此在实际应用中需引起重视。在二叉搜索树实现中,应确定使用有序前驱还是有序后继以保持树的适当平衡(这通常被称为自平衡二叉搜索树)。
总结
至此,关于如何利用 JavaScript 实现二叉搜索树的文章介绍完毕。更多相关 JavaScript 二叉搜索树内容请搜索本站以前的文章或继续浏览下面的相关文章,希望大家以后多多支持本站!